Nature’s Hidden Ledger: Decoding Water’s Past to Secure Its Future

Nature Wrote the Logs. We’re Finally Building the Readers.
As someone who has spent two decades designing systems that store and move data, I’ll admit something slightly embarrassing: the most elegant time-series database I’ve ever studied wasn’t built by anyone. It’s an aquifer.
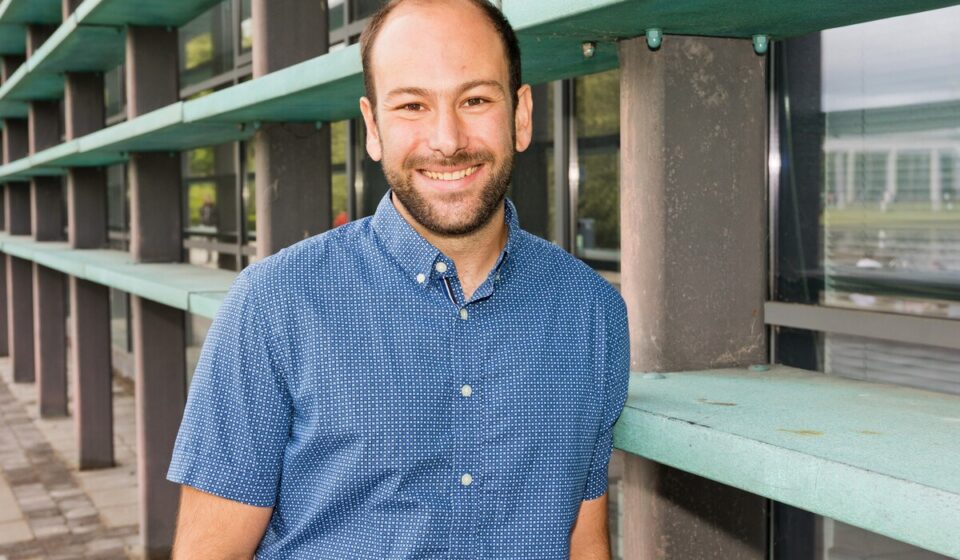
That thought resurfaced while reading about Dr. Alan Seltzer, a hydrogeochemist at University College Dublin. Writing in Science, his team showed that a rare nitrogen isotopologue – 15N15N – acts as a natural fingerprint for microbial nitrate conversion, finally letting researchers reconstruct how much nitrogen entered groundwater and what became of it. His ERC-funded TABPHISH project now spans six study regions, and his stated bet going forward is on portable, field-deployable mass spectrometry.
The schema was always there; the parser arrived late.
As Seltzer puts it, “there are remarkable ways in which nature spontaneously records information about itself over time.” Despite entropy, every microbial transformation leaves an isotopic signature; every drop percolating through soil writes a record. The data existed for millennia. What was missing was instrumentation – only recent high-resolution mass spectrometry can separate molecules whose masses differ by a whisker. In software terms: the log format was stable for eons; the reader shipped last year. That reframes innovation entirely. Sometimes the breakthrough isn’t generating data – it’s finally being able to read what was always recorded.
Observability, but for groundwater.
Every distributed-systems engineer knows the trap: if a process transforms state without emitting a trace, you cannot reconstruct the input from the output. That is precisely the decades-old impasse in nitrogen accounting – nitrate enters an aquifer, microbes consume an unknown share, and you’re left measuring residuals. The isotope pair works like a trace ID embedded in the payload: it survives the transformation and carries provenance home. For CTOs, the rule generalizes ruthlessly – if you’re inferring system history from residuals, you don’t have observability. You have archaeology. Design tracing in on day one, whether the payload is a packet or a molecule.
The lab-to-edge migration.
What I find most strategically interesting is Seltzer’s push for field-deployable instruments – water agencies in regions without laboratory access making high-quality dissolved gas measurements on-site. This is the same architectural migration IT lived through: mainframe → cloud → edge. When centralized analytical capacity becomes the bottleneck, capability gets pushed to the point of sampling. The trade-off ladder is familiar too: precision vs. portability, resolution vs. cost – the same calculus as on-device inference versus datacenter inference. Instruments follow a lifecycle: research-grade, then field-grade, then commodity. And when an instrument commoditizes, decision-making decentralizes with it.
Why this reads differently from Assam.
India is among the world’s largest users of groundwater, and the Northeast carries documented arsenic, fluoride and nitrate hotspots; millions depend on tubewells and spring-fed systems. The leap from panchayat-level colour-change test kits to portable mass spectrometry is exactly the frugal-innovation frontier worth backing. And the downstream prize is a DPI-shaped one: environmental sensing at scale, plumbed into public data rails, turning water quality from an annual report into live infrastructure.
Takeaways:
- Before building a new pipeline, ask what the physical world has already recorded. Nature’s logs are append-only – and free.
- Watch precision go portable. When lab-grade instruments become field-grade, an entire industry’s architecture resets.
- Residuals are not observability. If you can’t trace what was consumed or transformed, you’re guessing.
- For India: decentralized water sensing plus public data infrastructure is a legitimate DPI frontier, not a lab curiosity.
The second law guarantees entropy wins in the end. But legibility is engineered. Whether the system is an aquifer or an enterprise stack, the ones that endure are those that leave traces – and the ones wise enough to build the readers in time.
About the Author: Sanjeev Sarma is the Founder Director and Chief Software Architect at Webx Technologies. With a core focus on Generative AI integration, Cloud-Native Scalability, and Enterprise Software Architecture, he has spent over two decades driving digital transformation across Northeast India and beyond. Beyond his corporate leadership, Sanjeev is deeply invested in shaping the future of the IT industry. He serves as an Industry Expert on the Board of Studies for Assam Don Bosco University’s School of Technology, advises state technology committees, and actively mentors emerging tech startups at STPI. He brings a unique, dual perspective of high-level enterprise execution and future-ready academic curriculum development.