Dreambeans in India: Architecting Proactive AI Without Privacy Debt

The End of the Prompt: What Proactive AI Really Tests in Your Architecture
For two years, the entire industry has been teaching users to write better prompts. I think we’ve been optimizing the wrong end of the system.
The next architectural frontier isn’t a smarter chat box – it’s software that reads ambient context and initiates, without being asked. Google’s quiet expansion of its experimental Dreambeans app into India as its first market outside the U.S. is a useful stress test of that idea.
The Signal
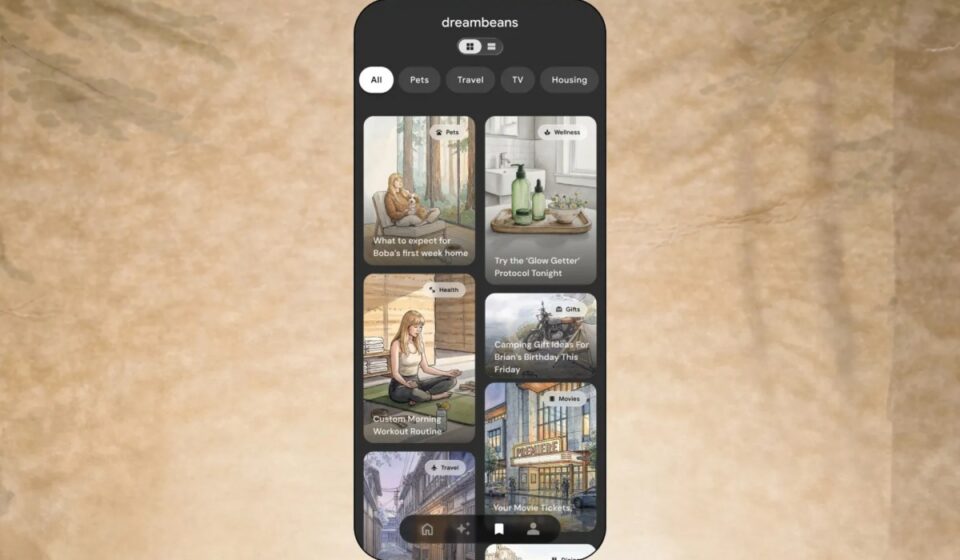
Google has opened Dreambeans – a promptless app that draws on Calendar, Gmail, Photos, Search, and YouTube to auto-generate illustrated personal stories – to Indian users, with support for 13 local languages. Adoption in the U.S. has been modest: roughly 55,000 downloads since June, with an 84% month-on-month drop in October. Small numbers, but the architecture underneath is the story.
The Context Graph Is the Hard Part
Every enterprise AI roadmap I review still assumes a human at a keyboard expressing intent. Proactive systems invert that: they require a persistent personal context layer – an entity graph stitching identity, calendar, media, and communication into something a model can reason over. This is precisely where most enterprise pilots quietly die. Retrieval over documents is tractable. Retrieval over a person’s life is a governance problem wearing a machine-learning costume.
Three things I’d flag for any CTO designing here:
Consent as an API, not a settings page. Per-service toggles, revocable connections, and deletion that propagates back into the personalization layer are the correct primitive – and they should be enforced architecturally, not by policy documentation. If your connector layer can’t answer “which data source produced this output?” at runtime, you don’t have a consent model. You have a checkbox.
Guardrails for the unsolicited. A system that proactively surfaces memory will, eventually, surface grief. The ability to suppress topics – bereavement, business matters, personal history – has to be a first-class inference filter, not a preferences screen bolted on later. Google’s own acknowledgment that the app can generate stories involving people who have died should be read as a design warning, not a caveat.
The economics of unrequested compute. Proactive generation burns inference cycles with no user trigger. That forces small-model gating, aggressive caching, and batch pre-computation into the architecture from day one. It’s the least glamorous constraint and the one that kills unit economics fastest.
The Multilingual Trap
Here’s the part that matters most for India. Dreambeans supports 13 languages – but only one at a time. It cannot mix them.
That is not a UX limitation. It’s a tokenization and embedding architecture limitation. Indians do not speak in monolingual blocks. Hinglish, Assamese-English code-mixing, Bodo-Hindi switching – this is the default register, not an edge case. Any pipeline that assumes one language per session will fracture at the last mile, no matter how many languages it nominally supports. For builders working with Bhashini or similar stacks, code-switched ASR and code-mixed embeddings deserve priority over adding language number fourteen.
The Northeast is a live laboratory for this. With over a hundred languages across the region and script diversity that defeats naive normalization, frugal innovation here means designing for the code-switcher first – not retrofitting them later.
I’d also note the boundary Google drew: personal accounts only, no enterprise users. That’s sensible, but it foreshadows a governance split – consumer-grade proactive agents versus enterprise-governed counterparts that need the same context graph with zero data egress.
What I’d Take Away
- Stop benchmarking narrow utility apps against general assistants. Downloads measure curiosity; retention measures value.
- Treat the personal context graph as a sovereign architecture decision, not a vendor integration.
- Build consent enforcement into the runtime, not the terms of service.
- Design for code-mixing before you design for language count.
- Budget for inference that no one requested – it’s your largest hidden cost centre.
The prompt was always a temporary interface – a scaffold for systems that couldn’t yet read context. The interesting question is no longer whether AI can answer well, but whether we can architect systems worthy of being trusted to speak first.
About the Author: Sanjeev Sarma is the Founder Director and Chief Software Architect at Webx Technologies. With a core focus on Generative AI integration, Cloud-Native Scalability, and Enterprise Software Architecture, he has spent over two decades driving digital transformation across Northeast India and beyond. Beyond his corporate leadership, Sanjeev is deeply invested in shaping the future of the IT industry. He serves as an Industry Expert on the Board of Studies for Assam Don Bosco University’s School of Technology, advises state technology committees, and actively mentors emerging tech startups at STPI. He brings a unique, dual perspective of high-level enterprise execution and future-ready academic curriculum development.