Beyond Autonomy: Operational Accountability for Robotaxis in Public Safety

Autonomy’s Hardest Test Begins When the System Fails
The revealing test of an autonomous vehicle is not how gracefully it moves through clear roads. It is whether the entire mobility system remains safe when the vehicle, its network, or its operating model fails.
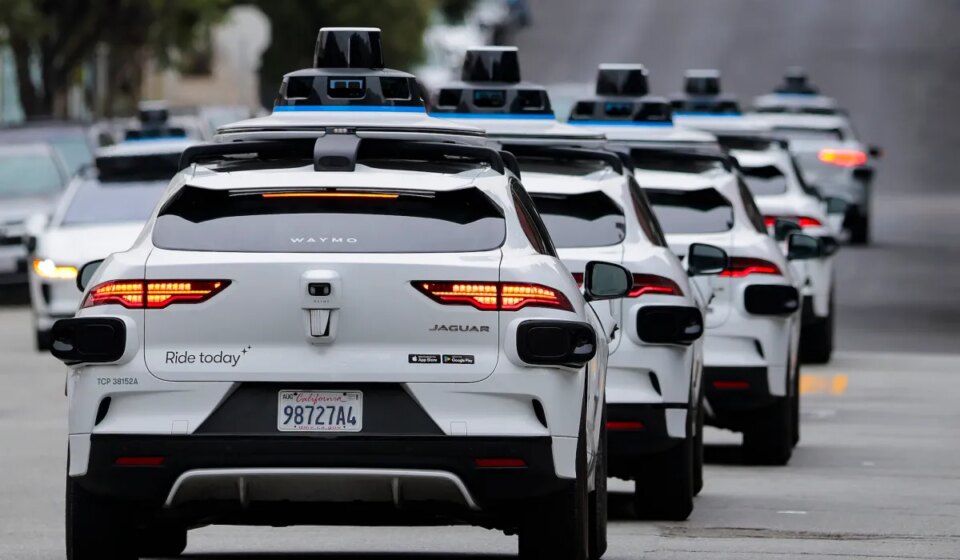
California’s new Senate Bill 1246 responds to robotaxis that have broken down, obstructed traffic, entered crime scenes, or delayed first responders. Effective in July 2028, it introduces local technical support, system-wide outage notifications, U.S. residency and licensing rules for remote drivers, and potential penalties when an AV impedes emergency responders for more than 30 minutes.
From Driving Stack to Service Architecture
From an enterprise-architecture perspective, this is more than a transport rule. It acknowledges that autonomy is not only a perception-and-planning problem; it is also an exception-management capability.
A production robotaxi now spans the vehicle, edge computing, cloud orchestration, telemetry, remote assistance, dispatch, cybersecurity, and a human escalation chain. If one layer falters, the vehicle can become a city-scale incident.
The distinction between remote assistance and remote driving is especially important. In the former, software retains control while a person advises or issues bounded commands. In the latter, a human assumes direct control, introducing different latency, licensing, liability, security, and training requirements.
Architects therefore need explicit operational taxonomies-not vague labels such as “teleoperation.” Every intervention mode requires defined authority boundaries, audit trails, and failover behavior. Direct control also demands zero-trust identity, strong authorization, and immutable command records.
Local Response Is Part of the Architecture
Requiring local incident technicians exposes a hidden dependency: a nominally autonomous fleet still depends on a service network.
Centralized operations may be efficient, but they remain vulnerable to latency, network outages, cross-border policy constraints, and insufficient local context. The stronger pattern is tiered: the vehicle manages immediate risk autonomously, regional operations coordinate diagnosis and recovery, and qualified local personnel provide physical intervention when software cannot.
A 30-minute penalty is useful as an accountability threshold, but it should not become the sole service target. Blocking an ambulance for 29 minutes is still a serious failure.
Response objectives should instead be severity-based, with measurable clocks for:
- Detecting the incident
- Reaching a safe vehicle state
- Notifying the correct authority
- Providing continuous situation updates
- Transferring control to responders
The critical metric is not simply disengagement rate or miles driven. It is coordinated recovery.
Compliance Must Become Executable Policy
For CTOs and founders, the practical lesson is that regulation cannot remain in a policy document.
Jurisdictional requirements-operator location, licensing, data residency, retention, emergency protocols, and response times-must become versioned, machine-enforceable rules within the operational control plane. Geofenced policies can determine which operating mode, support channel, and escalation path is permitted in a given area.
System-wide status interfaces should also use consistent, machine-readable incident feeds for local authorities. These interfaces must balance emergency availability with privacy, security, and evidence-retention requirements.
This creates a genuine speed-versus-control trade-off. Heavy centralization improves consistency but adds latency and jurisdictional fragility. Excessive local autonomy improves response time but can produce uneven training and fragmented records. A hybrid architecture-with global standards and regional execution-is generally the more defensible balance.
Four Questions for Autonomous-System Leaders
Before deploying autonomous services at scale, I would ask:
- Can every intervention mode be audited, from software guidance to direct remote control?
- Does the vehicle degrade safely when cloud connectivity or location intelligence is unavailable?
- Are incident severity, authority, and response commitments encoded in real-time policy?
- Do technical, operational, and regulatory metrics converge into one recovery dashboard?
The next measure of autonomous mobility will not be how often a vehicle avoids an incident. It will be how calmly, quickly, and accountably the entire system responds when one occurs. That is the real standard of production autonomy.
About the Author: Sanjeev Sarma is the Founder Director and Chief Software Architect at Webx Technologies. With a core focus on Generative AI integration, Cloud-Native Scalability, and Enterprise Software Architecture, he has spent over two decades driving digital transformation across Northeast India and beyond. Beyond his corporate leadership, Sanjeev is deeply invested in shaping the future of the IT industry. He serves as an Industry Expert on the Board of Studies for Assam Don Bosco University’s School of Technology, advises state technology committees, and actively mentors emerging tech startups at STPI. He brings a unique, dual perspective of high-level enterprise execution and future-ready academic curriculum development.