Beyond Gradient Boosting: The Enterprise Shift to Tabular Foundation Models

The Real Shift in Enterprise AI Is Not “No Training”
We often equate AI progress with bigger models, more parameters, and longer training cycles. Yet for most enterprises, the real constraint is different: every new prediction problem requires another model-training lifecycle-collect labels, engineer features, tune parameters, validate, deploy, and monitor.
A recent advance in tabular foundation models suggests that this lifecycle is beginning to change.
From Models per Dataset to Intelligence Across Datasets
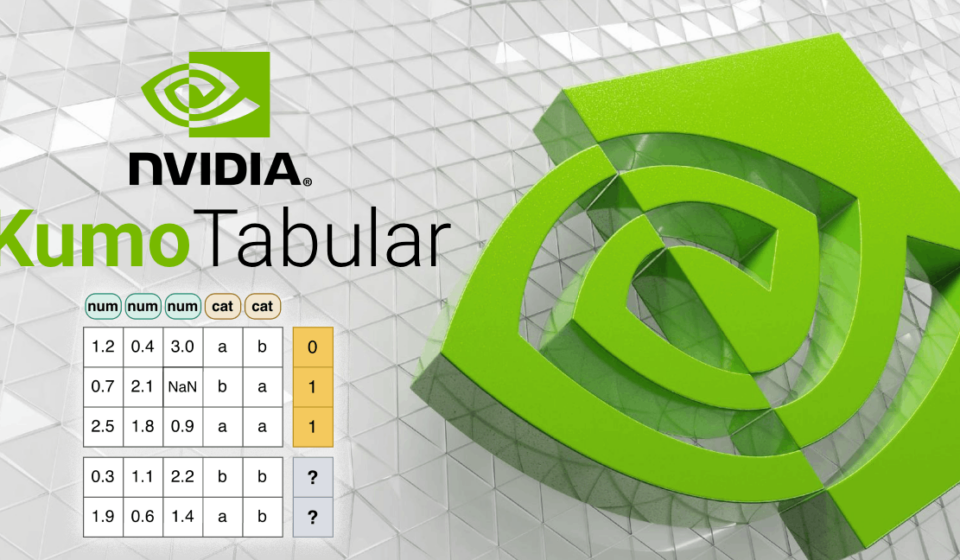
The new approach treats labeled rows as context rather than training material. A pretrained model receives examples of a table and predicts previously unseen rows without updating its weights for that specific task.
This is more than a faster alternative to gradient boosting. It represents a shift from isolated, task-specific models toward reusable intelligence that can adapt operationally.
The underlying principle comes from in-context learning: just as a language model can learn a new pattern from examples placed in its prompt, a tabular model can infer relationships from labeled examples placed in its context.
Why Synthetic Training Environments Matter
One of the most consequential research choices is pretraining on procedurally generated tables rather than relying primarily on private enterprise datasets.
Using structural causal models, synthetic data can simulate hidden variables, causal relationships, nonlinear interactions, missing values, noisy categories, outliers, and imbalanced targets. This approach supports two critical capabilities. First, it allows pretraining at a scale that proprietary business data alone could never provide. Second, it reduces direct dependence on sensitive organizational datasets during model development.
However, synthetic data is not automatically unbiased or realistic. It is a hypothesis about possible data-generating mechanisms. If the generator lacks certain social, temporal, or operational patterns, the model may inherit those blind spots.
The lesson for researchers is that synthetic data is most valuable when treated as a diverse test environment, rather than as a substitute for representative real-world evidence.
Why Table Structure Matters
Most language models flatten structured information into sequences. A table-aware architecture instead introduces useful inductive biases. Column attention can determine whether a value is typical or unusual within its distribution. Row attention can learn interactions among features, while context attention connects query rows with labeled examples.
The model must therefore learn three different concepts: the meaning of a value, the interaction of features, and the relevance of historical examples.
Subtle techniques such as length-aware attention also address a fundamental scaling problem: as context grows, ordinary attention can become diffuse and less decisive.
For architects, the important insight is that structure matters. A model designed around how data actually behaves will often be more appropriate than a generic model forced to interpret every table as flattened text.
The Production Reality
The phrase “no training” should not be interpreted as “no data work.” Enterprises will still need strong data contracts, semantic validation, temporal controls, and monitoring for distribution shift.
They will also need to manage the context itself. Which historical rows are included? Are labels reliable? Could future information leak into the context? Are missing values meaningful? Once context selection becomes part of inference, it becomes operational configuration and must be governed accordingly.
I see three major implications for CTOs and enterprise architects. The first is that model choice will become a portfolio decision. Foundation models may provide the best starting point when labels are scarce, while gradient-boosted trees can remain preferable for constrained latency, interpretability, or highly stable production workloads. The second implication is that calibration and uncertainty will matter more than headline accuracy. A prediction without a reliable confidence measure is often an operational liability. The third implication is that synthetic-data pretraining should trigger stronger-not weaker-evaluation discipline. Benchmarks are useful signals, but they cannot replace validation against local data, rare events, and adversarial edge cases.
A Relevant Opportunity for India
For Indian enterprises and public institutions, this could be significant. Credit decisions, agricultural forecasting, insurance, logistics, and public-service planning often rely on limited labeled datasets and inconsistent records. Tabular foundation models could make experimentation more accessible to organizations that cannot afford a large specialist team.
But scale without local validation can amplify weak labels and historical bias. Democratized modelling must therefore be matched with strong data stewardship and sector-specific evaluation.
What Leaders Should Do Now
Leaders must establish a common evaluation framework before selecting models. They should also pilot foundation models where labels are genuinely scarce, rather than applying them everywhere automatically. It is essential to keep interpretable models as fallbacks for high-risk decisions. Furthermore, organizations must treat context selection, drift detection, calibration, and abstention as first-class architecture concerns. Finally, they must avoid interpreting leaderboard position as a production-readiness certificate.
The deeper opportunity is not a particular model or benchmark. It is a transition from repeatedly teaching computers each business problem to building systems that can reason over many such problems.
The next era of enterprise AI will belong not only to organizations with the largest models, but to those that understand how to turn context into trustworthy decisions.
About the Author: Sanjeev Sarma is the Founder Director and Chief Software Architect at Webx Technologies. With a core focus on Generative AI integration, Cloud-Native Scalability, and Enterprise Software Architecture, he has spent over two decades driving digital transformation across Northeast India and beyond. Beyond his corporate leadership, Sanjeev is deeply invested in shaping the future of the IT industry. He serves as an Industry Expert on the Board of Studies for Assam Don Bosco University’s School of Technology, advises state technology committees, and actively mentors emerging tech startups at STPI. He brings a unique, dual perspective of high-level enterprise execution and future-ready academic curriculum development.