From Contingency to Architecture: The Rise of the Distributed Energy Edge

Your Cloud Strategy Still Depends on the Power Socket
We often describe resilience in terms of availability zones, replicated databases, and automated failover.
But a cloud application can remain perfectly healthy while the business using it goes offline.
The router loses power. The local terminal shuts down. The last-mile connection disappears.
Digital resilience still has a physical dependency.
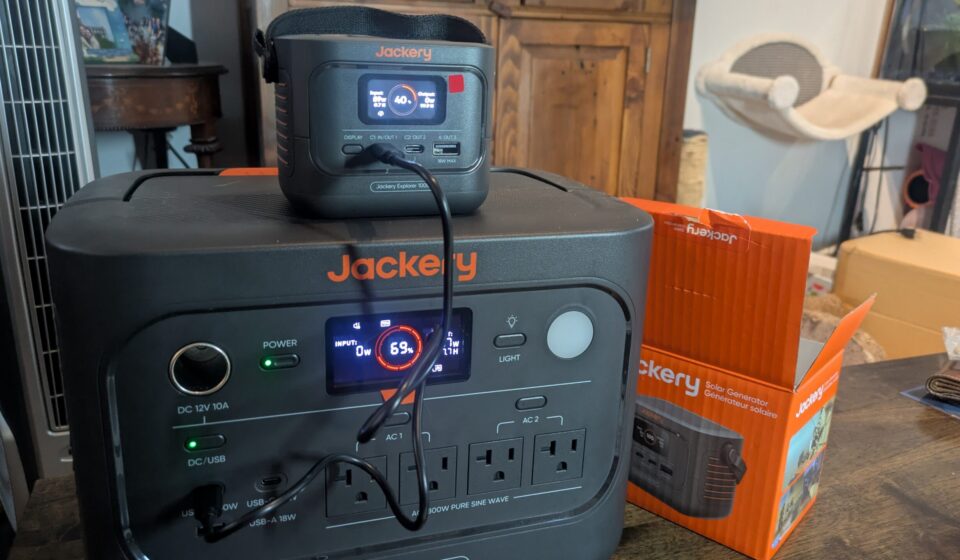
A recent CleanTechnica report describes a sharp increase in US portable-battery sales, with several models reportedly selling out shortly after promotional launches. It suggests household preparedness as a possible driver, while acknowledging that consumer motivations have not been established through detailed research.
What interests me is not the retail story. It is the architectural possibility: energy storage moving from an emergency accessory toward an actively managed part of everyday infrastructure.
Backup is equipment. Resilience is architecture.
Buying a battery does not create resilience any more than buying a second server creates high availability.
The real work lies in deciding what must continue operating, for how long, and under which failure conditions.
For an enterprise, this means extending dependency mapping beyond software. A customer-facing service may depend on a local network switch, an authentication device, a telecom link, and a workstation. Keeping the application server running is irrelevant if another essential link fails.
I believe we need to treat energy continuity as an explicit design requirement-not an assumption buried in facilities management.
That requires measurable objectives: minimum service duration, acceptable interruption, recovery priorities, and tested operating procedures. Battery capacity alone tells us little without workload demand, conversion losses, temperature conditions, and equipment compatibility.
Even transfer time matters. A device marketed for backup use is not automatically suitable for every interruption-sensitive workload.
Distributed storage needs distributed-systems discipline
The deeper opportunity emerges when storage becomes coordinated rather than isolated.
Local batteries can potentially support solar self-consumption, shift demand away from expensive periods, and preserve critical operations during outages. But these outcomes require different operating policies.
A battery discharged to reduce electricity costs may have insufficient reserve when an outage begins. A system optimised for backup may leave financial savings unrealised.
The central problem is therefore not simply storage capacity. It is control policy.
For technology leaders, this creates familiar architectural questions:
- Which decisions must remain local when connectivity fails?
- What interfaces allow components from different vendors to work together?
- Who controls telemetry, configuration, and remote access?
- How do we prevent an optimisation service from becoming another critical dependency?
Remote orchestration also creates a security boundary. Compromised control systems could affect physical availability, not merely information confidentiality.
The sensible pattern is local protection and essential control, with remote coordination where appropriate. A cloud outage should not prevent a site from using its own stored energy.
And the economics deserve discipline. Savings depend on tariffs, charging losses, battery degradation, utilisation, and integration costs-not simply the difference between peak and off-peak prices.
A practical lesson for Northeast India
For flood-prone communities and remote service locations in Northeast India, this has a direct relevance.
A digitally enabled service centre needs more than software access. It needs sufficient power and connectivity to remain useful when surrounding infrastructure is disrupted.
The answer is not automatically a larger battery. It may be a lower-power terminal, more efficient networking equipment, offline-capable workflows, and storage sized around essential services.
That is frugal innovation at the architectural level: reduce the critical load before expanding the backup system.
What leaders should do next
Start with one critical service:
- Map its physical and digital dependencies.
- Define its minimum viable operating mode.
- Test power loss and connectivity loss together.
- Evaluate lifecycle cost, interoperability, and maintainability before scaling.
A short-lived sales surge cannot establish a permanent market transition. But it raises a durable question:
Are we designing systems that remain available on a dashboard-or services that remain useful to people when conditions deteriorate?
About the Author: Sanjeev Sarma is the Founder Director and Chief Software Architect at Webx Technologies. With a core focus on Generative AI integration, Cloud-Native Scalability, and Enterprise Software Architecture, he has spent over two decades driving digital transformation across Northeast India and beyond. Beyond his corporate leadership, Sanjeev is deeply invested in shaping the future of the IT industry. He serves as an Industry Expert on the Board of Studies for Assam Don Bosco University’s School of Technology, advises state technology committees, and actively mentors emerging tech startups at STPI. He brings a unique, dual perspective of high-level enterprise execution and future-ready academic curriculum development.