The Resilience Imperative: Architecting Systems Beyond Your Control

Reliability Is Not a Feature. It Is an Architecture
At the end of every digital transaction is a human trying to complete something important: paying a bill, booking a ticket, transferring money, or accessing a service. A system that works 99.9% of the time can still create a serious business failure if it becomes unavailable at the wrong moment.
The real test of resilience is not whether systems fail. Failures are inevitable. The test is whether they fail in a controlled, observable, and recoverable manner.
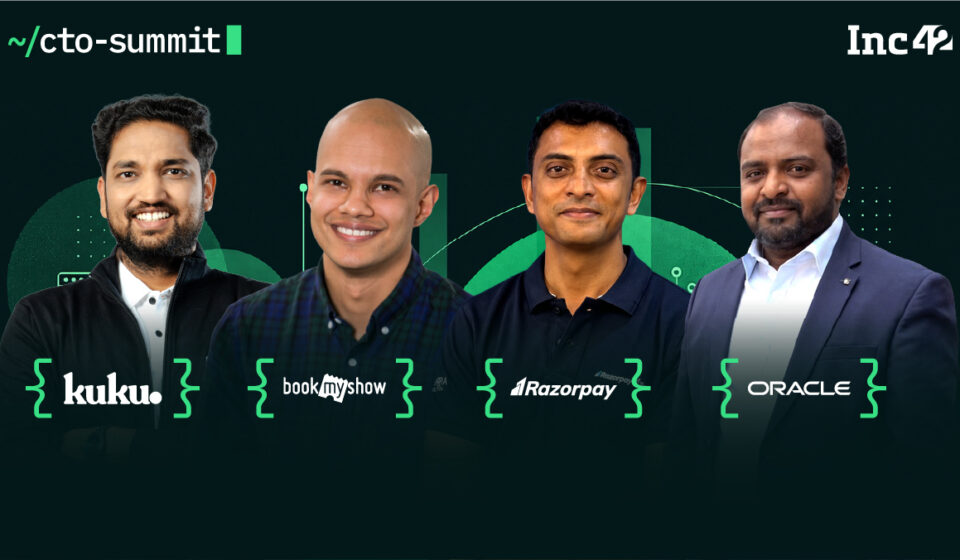
At a recent Inc42 CTO Summit, Razorpay’s SVP of Engineering Prabhu Ram made a deceptively simple point: no enterprise owns every layer of the technology stack. The strategic implication is much larger than disaster recovery. External dependencies must be treated as first-class design inputs, because a disruption anywhere along the chain can become a user-facing failure.
The Stack You Do Not Control
Most enterprise roadmaps focus on the systems a company directly controls: applications, databases, cloud resources, and internal teams. However, a single customer journey usually passes through many layers-identity verification, DNS, telecom networks, cloud infrastructure, payment networks, fraud systems, third-party APIs, and notification services.
This creates two architectural problems.
The first is dependency concentration. When multiple business services rely on the same external platform, a localized failure can become an enterprise-wide incident. The second is latency accumulation. Every additional network call introduces uncertainty, delay, and another point at which a transaction may fail.
Resilience therefore requires more than adding retries. It requires mapping critical dependencies, defining recovery objectives, building graceful degradation, and testing whether alternative paths actually work. Circuit breakers, idempotent transactions, queueing, regional failover, and portable interfaces all have a role-but none is sufficient without clear ownership and measurable service-level objectives.
There is also a trade-off. Redundancy increases cost and operational complexity. A fallback that cannot preserve data integrity or business correctness is not resilience; it is simply a different way of hiding risk. The objective is not to eliminate every dependency, but to understand which ones the business cannot afford to trust blindly.
I believe the strategic answer is not necessarily to own all seven layers, as some technology leaders can. For most enterprises, it is to create optionality: portable data, well-defined contracts, tested exit strategies, and carefully selected redundancy where the business impact justifies it.
AI Needs a Reliable Substrate
Bringing AI models closer to enterprise data can improve latency, privacy, and response quality. That is an important architectural movement. But better model placement cannot compensate for weak engineering foundations.
Without end-to-end observability, an AI layer can make incidents harder to diagnose and potentially automate poor decisions at scale. Telemetry must connect infrastructure health, application behaviour, business transactions, and model outputs. Leaders need to know not only what the system is doing, but also why it is doing it, how confident it is, and where human intervention is required.
In practical terms, AI readiness is not simply access to a capable model. It is the ability to detect anomalies, preserve an audit trail, evaluate outcomes, and fall back safely when the model or its dependencies fail. An intelligent layer built on an opaque foundation will only scale uncertainty.
India Makes the Lesson Concrete
For India, this is not an abstract cloud concern. UPI, digital public infrastructure, and online commerce depend on a broad ecosystem of banks, telecom operators, cloud providers, data centres, networks, and public platforms. Shared rails create enormous scale and inclusion, but they also create systemic dependencies.
In regions with variable connectivity, including parts of Northeast India, resilient design may require low-bandwidth modes, local edge capabilities, asynchronous workflows, and graceful service degradation. The broader lesson is that architecture must be designed for the actual conditions of users, not only the ideal conditions represented in a data-centre diagram.
Questions Every Engineering Leader Should Ask
Three questions should sit at the centre of every resilience programme.
What are our critical dependencies, and which failure modes could stop a customer journey?
Can we detect a failure across both our systems and third-party services?
Have we tested the fallback-not merely designed it on paper?
The next generation of dependable enterprises will not be defined by systems that never fail. It will be defined by organisations that can see failure early, make informed decisions quickly, and recover without losing customer trust.
That is the real promise of resilience: engineering designed for uncertainty, not just performance.
About the Author: Sanjeev Sarma is the Founder Director and Chief Software Architect at Webx Technologies. With a core focus on Generative AI integration, Cloud-Native Scalability, and Enterprise Software Architecture, he has spent over two decades driving digital transformation across Northeast India and beyond. Beyond his corporate leadership, Sanjeev is deeply invested in shaping the future of the IT industry. He serves as an Industry Expert on the Board of Studies for Assam Don Bosco University’s School of Technology, advises state technology committees, and actively mentors emerging tech startups at STPI. He brings a unique, dual perspective of high-level enterprise execution and future-ready academic curriculum development.