The Moving Frontier: Verified Synthetic Data for Enterprise AI Agents

The Real Moat in Enterprise AI Is the Learning Loop
We often describe enterprise AI progress in terms of larger models, longer context windows, and more sophisticated prompts. But inside a stateful enterprise, those capabilities matter only when an agent can select the right tools, respect operating policies, recover from intermediate failures, and leave the system in a verifiable business state. The real moat, therefore, is not model access alone. It is the organization’s ability to turn operational failures into a controlled learning system.
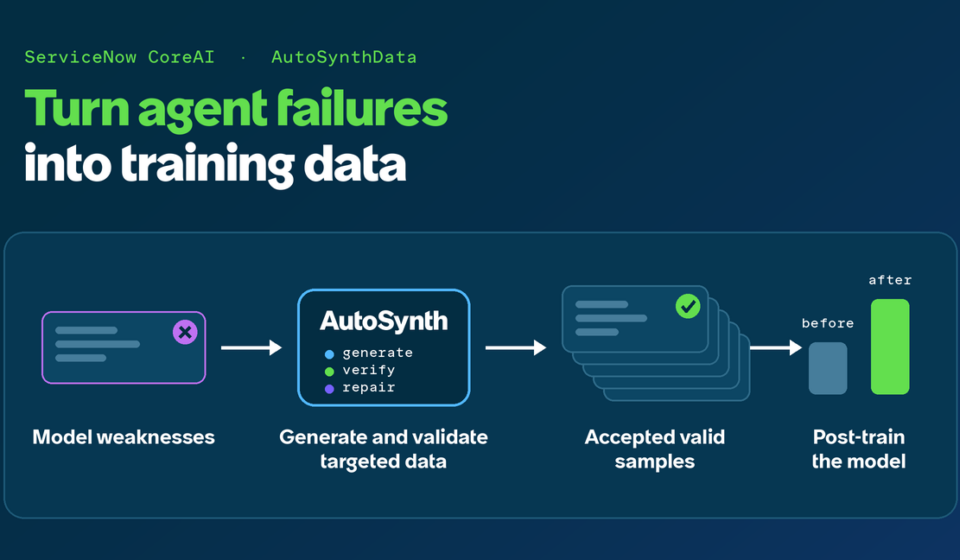
A recent ServiceNow CoreAI case study on AutoSynthData and EnterpriseOps Gym points to a more consequential idea: synthetic training data should be generated from the boundary between what a target model can and cannot reliably do. The system diagnoses failures, uses a stronger teacher to characterize successful behavior, creates new executable tasks, and validates both the solutions and the verifiers before data enters post-training. The important part is not simply producing more examples; it is building a disciplined curriculum around the model’s current weaknesses.
Failure Is a Design Input
Most enterprises already have extensive logs: incorrect responses, escalations, rejected actions, failed integrations, and user corrections. Yet these are usually treated as operational incidents rather than as inputs to system design.
For agentic AI, they should become architectural signals. An isolated failure is not yet a training example. The system must identify the underlying capability, vary the entities and workflow, preserve the policy constraints, and create several feasible tasks that test that capability in different situations. This is the difference between collecting errors and engineering a curriculum.
The capability-specification approach is especially important. By preserving the general capability while separating it from original prompts, entities, trajectories, and verifier details, an organization can reduce benchmark leakage and avoid training directly on its evaluation set. In architectural terms, evaluation data, training data, and production telemetry need clear lineage and governance.
The Verifier Is an Architectural Control
The most useful definition of an agentic task is not simply a user request. It is a contract:
task = system specification + user prompt + verifier
The system specification defines the environment and its policies. The prompt defines the user’s intent. The verifier defines what “success” means.
That last component deserves far more attention than it usually receives. A weak verifier can reward an incorrect final state, while an overly restrictive one can reject valid solutions that used a different-but equally appropriate-workflow. A verifier must be consistent with the task, sound in rejecting violations, and complete in accepting legitimate alternatives.
This principle applies directly to production agent platforms. A response that sounds correct is not necessarily a completed business transaction. Verification should examine state changes, tool outcomes, authorization boundaries, required records, and policy compliance. Positive tests confirm that the intended solution works; negative tests confirm that incorrect or incomplete outcomes fail.
I see the verifier as an architectural control plane for autonomous workflows, rather than merely a grading script. It should be versioned, auditable, deterministic where possible, and connected to rollback and escalation mechanisms.
Synthetic Scale Must Not Become Synthetic Drift
Synthetic data can scale quickly, but scale without quality creates a different kind of risk. If generation repeatedly produces similar task families or relies on a teacher model’s blind spots, the dataset may become large but strategically weak.
The stronger approach separates a vetted target set from a multiplication phase. Accepted examples generate novel variants, while batch-level review tracks coverage, diversity, repeated failure patterns, and overrepresented capabilities. This creates a feedback loop between individual quality control and dataset-level governance.
The reported results are encouraging: in the Hybrid environment, synthetic SFT improved mean Pass@1 by 7.2 percentage points; in ITSM, it rose from 18.77% to 27.18%. But these are environment-specific gains, not proof of universal intelligence. Teacher bias, verifier gaming, hidden edge cases, generation cost, privacy, and poor transfer across domains remain open risks.
What Enterprise Leaders Should Do Now
Enterprise leaders should treat agent failures as a governed data asset. They need to build an environment abstraction that exposes tools, state transitions, and policy constraints. They must also establish a verifier registry with positive and negative tests, maintain versioned task and dataset lineage, and recalibrate the curriculum after every model update.
Most importantly, organizations should measure improvement in business outcomes and trustworthy execution, rather than relying on answer quality alone. The frontier moves as the model improves, which means the learning system cannot be a one-time project.
The next advantage in enterprise AI will belong to organizations that can continuously convert failures into carefully validated learning opportunities. Models will become more capable, but the capability to teach, test, and govern them will remain an architectural advantage.
About the Author: Sanjeev Sarma is the Founder Director and Chief Software Architect at Webx Technologies. With a core focus on Generative AI integration, Cloud-Native Scalability, and Enterprise Software Architecture, he has spent over two decades driving digital transformation across Northeast India and beyond. Beyond his corporate leadership, Sanjeev is deeply invested in shaping the future of the IT industry. He serves as an Industry Expert on the Board of Studies for Assam Don Bosco University’s School of Technology, advises state technology committees, and actively mentors emerging tech startups at STPI. He brings a unique, dual perspective of high-level enterprise execution and future-ready academic curriculum development.