Architecting Resilience: Lessons From the FAA Ground Stop

When the Sky Stops: The Architecture Lesson Hidden in a Nationwide Ground Stop
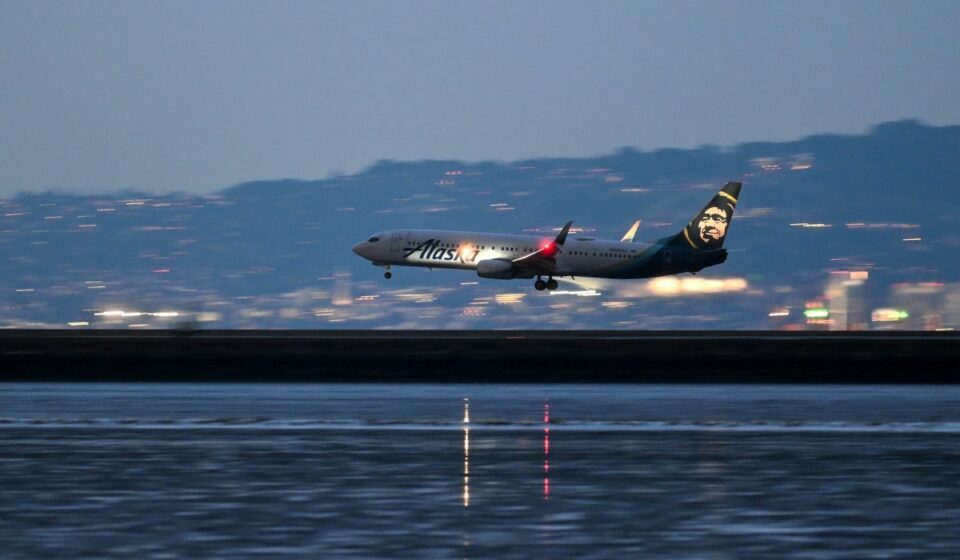
Picture thousands of aircraft sitting at their gates across an entire continent. The weather is fine, and the planes are fine. What has failed is the invisible layer of systems that coordinates them all.
We rarely think about infrastructure until it stops working. And when it does, it reminds us that the most critical systems in the world are often the ones we have stopped looking at.
What happened
According to a TechCrunch report, the US Federal Aviation Administration issued a nationwide ground stop, citing “extraordinary circumstances” and “reasons of safety.” The FAA attributed it to an equipment outage and communication issues affecting multiple Air Route Traffic Control Centers. The report also notes that the outage came in the same week an AI-powered tool was rolled out for air traffic controllers, though it stresses there is no established link between the two.
I won’t speculate on the root cause. The investigation will tell us that. But the incident is a useful case study in resilience architecture.
The ground stop was the system working
This may sound counterintuitive, but the ground stop itself is good design. When the coordination layer became unreliable, the system fell back to its safest known state: aircraft on the ground. That is fail-safe engineering, and aviation has spent decades perfecting it.
Most enterprise systems I review do the opposite. They fail open, fail silently, or fail unpredictably. Every architect should be able to answer what their system’s equivalent of a ground stop is. If you cannot define the safe state for your payment platform, hospital system, or citizen-services portal, you have not finished designing it.
When your status page goes down with you
One detail in the report deserves attention: the FAA’s own website was briefly down, and the advisory was reportedly not visible on the command center’s site at press time.
This is a classic problem of shared fate. The channel that tells the world you are in trouble should not be vulnerable to the same trouble. I have seen enterprises host their monitoring dashboards, incident communication, and even backup credentials on the infrastructure they are meant to watch over. Your control plane and your crisis communication must sit on independent rails.
Innovation at the edge, fragility at the core
Whether or not the new AI tool had anything to do with this outage, and nothing so far says it did, the timing illustrates a tension I see everywhere. Organisations are racing to add intelligence at the edge while the core beneath it ages quietly.
AI layered on brittle foundations does not make them less brittle. It adds dependencies and makes it harder to work out what failed and why. In safety-critical systems, AI should be advisory and loosely coupled, and the core must keep working without it. Graceful degradation has to be designed in from the start, because it cannot be patched in later.
The parallel for India’s digital rails
This matters closer to home. India has built remarkable Digital Public Infrastructure in UPI, Aadhaar, and DigiLocker, and when a single coordination layer serves over a billion people, its resilience becomes a question of national importance. As regional air connectivity expands across the Northeast, where a flight is often a lifeline, the systems behind it deserve the same rigour. In my work with e-governance platforms, the hardest conversations are about what happens on the worst day, and features rarely come into it.
Takeaways for technology leaders
- Define your safe state. Decide in advance how the system should fail, and make that a deliberate design choice.
- Decouple your communication channels. Status pages and alerting must survive the outage they report.
- Budget for modernisation. Technical debt in core systems compounds until it has to be paid all at once.
- Keep AI optional at the core. The system must run safely without its smartest component.
- Rehearse failure. Resilience that has never been tested cannot be relied on.
Closing thought
The true measure of a system is how it behaves on its worst day, and the time to design for that day is before it arrives.
About the Author: Sanjeev Sarma is the Founder Director and Chief Software Architect at Webx Technologies. With a core focus on Generative AI integration, Cloud-Native Scalability, and Enterprise Software Architecture, he has spent over two decades driving digital transformation across Northeast India and beyond. Beyond his corporate leadership, Sanjeev is deeply invested in shaping the future of the IT industry. He serves as an Industry Expert on the Board of Studies for Assam Don Bosco University’s School of Technology, advises state technology committees, and actively mentors emerging tech startups at STPI. He brings a unique, dual perspective of high-level enterprise execution and future-ready academic curriculum development.